Claude Sonnet 5.5 vs Opus 5.5: A Real-World Verdict?
August and September brought a flood of new AI models. Checking every single one just feels like a waste of time now, so I currently focus my daily work on a few reliable options like Claude, Kimi, and GLM. Recently, Anthropic dropped their new 5.5 models with a major claim: doing more work with fewer tokens and lower costs. I put them straight to work on my real projects, and I noticed that this efficiency claim actually holds up in practice.
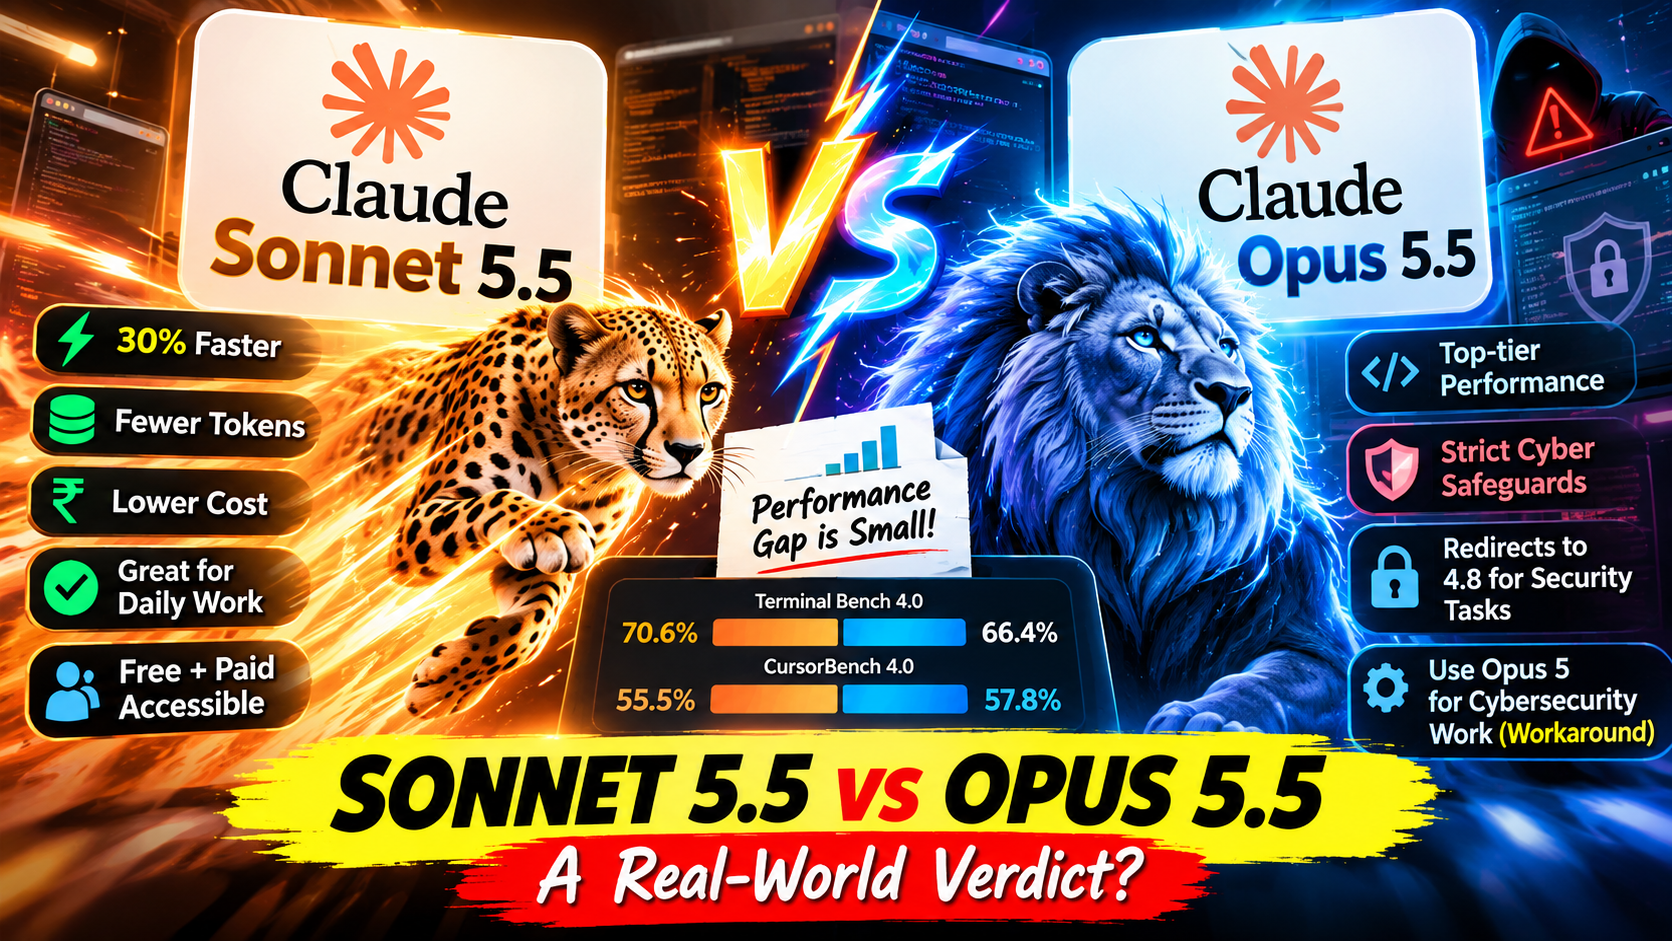
- Closing the Performance Gap: The benchmark numbers show that Sonnet 5.5 is surprisingly close to Opus 5.5 in capabilities. On Terminal Bench 4.0, Sonnet scored an impressive 70.6% at Max effort, while Opus scored 66.4% at Xhigh effort.
- Similar Coding Capability: On other tests like CursorBench 4.0, the scores remain nearly identical, with Sonnet hitting 55.5% and Opus closely ahead at 57.8%.
- High Everyday Value: Because these models perform so similarly on routine work, I have found Sonnet to be a highly practical tool that is easily accessible to everyone, whether on a free or paid plan.
Beyond just raw scores, Sonnet 5.5 handles general tasks and programming incredibly well. It is up to 30% faster and uses way fewer tokens for the exact same job. For example, a bug fixing task that used to take 12 to 13 tool calls now gets done in just 3. To get the most out of this, a simple practical tip is to keep the Thinking Effort setting at Medium. At Medium, the model gives very solid answers without burning through limits. Because it is so efficient with tokens, free users get much better access and chat times, while premium users will notice that hitting the annoying weekly limit happens a lot less often now.
- The Cybersecurity Roadblock: If your project involves cybersecurity or related development, Opus 5.5 has strict cyber safeguards that will aggressively redirect those tasks back to the older 4.8 model.
- The Opus 5 Workaround: For security related work, especially in Claude Code, my advice is to just use the older Opus 5. It had similar issues at launch, but it works smoothly now and will not redirect tasks.
- General Development: If your workflow is strictly general software development, Opus 5.5 will not get in the way and can be used comfortably to get top tier results.
Everything I have shared here is based strictly on my daily real world usage rather than just reading specification sheets. The AI landscape changes fast, but the best approach is always to simply try these models on your active projects. Test them out to see how they handle your specific everyday tasks. That is the only real way to decide what fits perfectly into your own workflow.